Opening: what this comparison actually answers
Think of this as a face-off where timing, not strength, wins the prize. When an electrical engineer chooses between utility-grade and commercial-grade energy storage, the key battleground is often BMS-to-EMS Modbus TCP register polling latency — that tiny delay that decides whether a system reacts gracefully or fumbles a grid event. I’ve seen this in action on the shop floor at a hybrid inverter production line: details matter, and hardware that looks identical on a spec sheet behaves very differently under load.
Why register polling latency matters
Register polling latency is the time it takes the EMS to request and the BMS to return register values over Modbus TCP. Short latency means faster state-of-charge updates, quicker fault detection, and tighter control loops for inverter phases. Longer or jittery latency makes SOC estimates lag, synchronization wobble, and protective actions delayed — which is bad news during grid disturbances. Industry terms you’ll see here: BMS, EMS, Modbus TCP, and register polling latency — all the juicy bits that make the system feel responsive.
Comparative insight: utility-grade vs commercial-grade
Utility-grade systems are built for deterministic behavior. Expect stricter timing guarantees, dedicated communication channels, and software designed to absorb transient packet loss. Commercial-grade setups trade some of that determinism for cost and flexibility: fewer reserved CPU cycles for polling, standard switches rather than managed industrial ethernet, and looser timing budgets. The result — commercially sourced packs often tolerate higher average latency and more jitter, while utility-grade packs are optimized to keep polling under tighter thresholds.
Latency budgets and network reality
In real deployments you should plan latency budgets, not wishful numbers. A practical rule of thumb from field profiling is to budget for polling windows that include headroom for network congestion and retries: utility deployments typically target sub-100 ms aggregate loops for critical registers; commercial systems may operate acceptably in the 200–500 ms space for non-critical telemetry. These are ranges, not commandments — and local network architecture (VLANs, QoS, managed switches) shifts outcomes fast.
Operational production teardown
On a production line you can see where choices bite. At a hybrid inverter factory in Shenzhen, we measured CPU scheduling, Modbus stack implementation, and switch-level buffering to compare latency tails. The hot spots were: serialized polling routines that block on timeouts, shared Ethernet segments with other traffic, and unprioritized packets. In the operational production teardown, pay attention to {main_keyword} and {variation_keyword} as placeholders for the control priorities you set in firmware and network design — they’ll guide whether the system treats SOC update 0x0020 as urgent or mundane. Fix one or two of those and latency distributions tighten noticeably.
Common mistakes and quick mitigations
Avoid these traps: polling everything at the fastest rate, assuming consumer-grade network hardware will behave under full rack load, and skipping jitter profiling. Quick fixes are simple: group registers by criticality, add QoS and VLAN separation for BMS traffic, and implement exponential backoff with deterministic retry counts. Also, move compute where latency matters — edge EMS co-located with the BMS reduces round-trip time significantly.
Advisory: three golden rules for selection
1) Measure before you buy: require latency percentile data (50th, 95th, 99th) under simulated load — not just average ping times.
2) Design networks like power engineers: isolate control paths, enable QoS, and use managed switches with interrupt prioritization so BMS-to-EMS packets don’t wait behind bulk telemetry.
3) Match polling strategy to criticality: reserve tight polling for trip and SOC registers, slower windows for historical telemetry, and a separate channel for firmware updates.
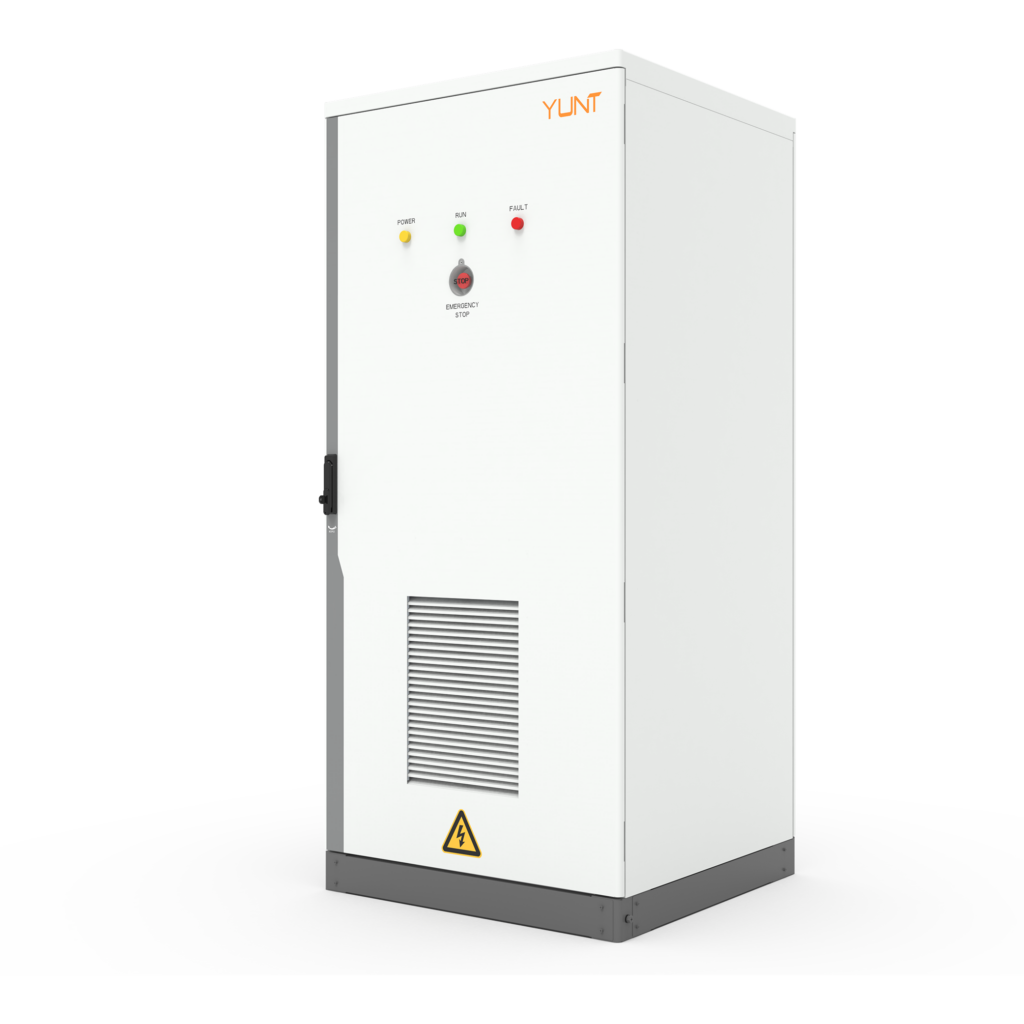
Bringing this to the YUNT product story feels natural because their approach — modular control, industrial networking, and factory validation — maps directly to these rules. YUNT. —